Hearing Bench
Can a model tell what a sound is just by looking at it?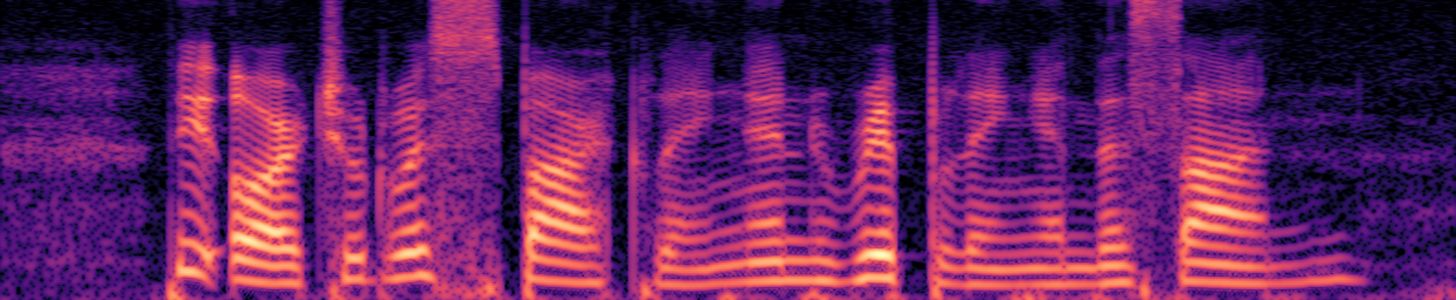
the orchard was sparkling and rippling in the sun
Each model gets a picture like this and has to say what the sound is. It never hears the audio. 100 clips across five tiers. Each model is shown at its best reasoning effort, up to xhigh. The best score is 44 out of 100.
Leaderboard
- Gemini 4 Argon highGoogle · Antigravity44
- Claude Opus 5.5 xhighAnthropic · Claude Code43
- Gemini 4 Argon mediumGoogle · Antigravity43
- Claude Opus 5.5 highAnthropic · Claude Code39
- Claude Opus 5.5 mediumAnthropic · Claude Code35
- Claude Opus 5.5 lowAnthropic · Claude Code31
- Gemini 4 Argon lowGoogle · Antigravity30
- Gemini 3.8 Flash highGoogle · Antigravity29
- Gemini 3.8 Flash mediumGoogle · Antigravity27
- GPT-6.1 Sol xhighOpenAI · Codex26
- GPT-6.1 Sol highOpenAI · Codex23
- GPT-6 Astra xhighOpenAI · Codex22
- GPT-6 Astra highOpenAI · Codex21
- Claude Sonnet 5.5 xhighAnthropic · Claude Code20
- GPT-6.1 Sol lowOpenAI · Codex20
- GPT-6 Astra mediumOpenAI · Codex17
- Grok 4.7 highxAI · Cursor17
- GPT-6.1 Sol mediumOpenAI · Codex16
- GPT-6 Astra lowOpenAI · Codex16
- Claude Sonnet 5.5 highAnthropic · Claude Code15
- Grok 4.7 mediumxAI · Cursor15
- Gemini 3.8 Flash lowGoogle · Antigravity15
- Grok 4.7 xhighxAI · Cursor13
- Claude Sonnet 5.5 lowAnthropic · Claude Code11
- Claude Sonnet 5.5 mediumAnthropic · Claude Code10
- Grok 4.7 lowxAI · Cursor10
- Claude Haiku 5.5 mediumAnthropic · Claude Code9
- GPT-6 Luna xhighOpenAI · Codex9
- Claude Haiku 5.5 lowAnthropic · Claude Code7
- Claude Haiku 5.5 highAnthropic · Claude Code7
- Claude Haiku 5.5 xhighAnthropic · Claude Code7
- GPT-6 Luna highOpenAI · Codex7
- GPT-6 Luna lowOpenAI · Codex3
- GPT-6 Luna mediumOpenAI · Codex2
- –Muse WonderMeta · Muse Codewaiting for the Muse quota to reset
Cost against score
What each run would have cost through the API, against clips correct. A line joins one model's reasoning efforts, from low to xhigh. The orange step is the Pareto frontier: the runs that nothing cheaper matches.
On the frontier: GPT-6 Luna (low), Claude Haiku 5.5 (low), Claude Haiku 5.5 (medium), GPT-6.1 Sol (low), Gemini 4 Argon (low), Claude Opus 5.5 (low), Gemini 4 Argon (medium), Gemini 4 Argon (high). These runs used subscriptions; cost is the image and prompt in, plus the answer and thinking out, at list prices on 13 October 2026.
The five tiers
The small bars beside each model above are these tiers, 20 clips each. Press play to hear what a picture is of.

This one is a dog barking. Clips from ESC-50.

This one is a note on a brass instrument. Clips from NSynth.
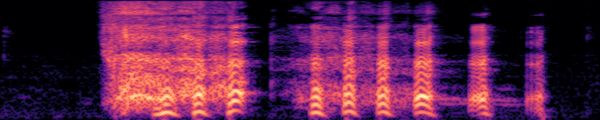
This one is a person laughing. Clips from VocalSound.

This one is the word "seven". Clips from Speech Commands.

This one is "the orchard was sparkling and rippling in the sun". Clips from LibriSpeech.
Every answer
One column per clip, one row per model. Within a tier, the clips most models got right are on the left.
Confidence against accuracy
Each model was asked to say how sure it was. The gap is how far its average stated confidence sits above its share of correct answers.
The numbers
| Correct by tier, of 20 | All 100 clips | Answer style | Per answer | Run | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Model | 1 | 2 | 3 | 4 | 5 | Correct | Near | Wrong | Hedged | Listed | Conf. | Tokens | Time | Cost |
| Gemini 4 Argon (high) | 15 | 8 | 6 | 15 | 0 | 44 | 1 | 55 | 32 | 51 | 66% | 20,230 | 178s | $20.47 |
| Claude Opus 5.5 (xhigh) | 15 | 8 | 6 | 14 | 0 | 43 | 6 | 51 | 79 | 56 | 55% | 9,057 | 103s | $18.66 |
| Gemini 4 Argon (medium) | 15 | 7 | 7 | 14 | 0 | 43 | 4 | 53 | 56 | 50 | 53% | 2,073 | 33s | $2.31 |
| Claude Opus 5.5 (high) | 15 | 8 | 5 | 11 | 0 | 39 | 4 | 57 | 80 | 49 | 55% | 1,855 | 23s | $4.26 |
| Claude Opus 5.5 (medium) | 13 | 7 | 4 | 11 | 0 | 35 | 3 | 62 | 82 | 48 | 54% | 1,021 | 13s | $2.59 |
| Claude Opus 5.5 (low) | 10 | 7 | 4 | 10 | 0 | 31 | 7 | 62 | 77 | 42 | 59% | 815 | 11s | $2.18 |
| Gemini 4 Argon (low) | 12 | 6 | 5 | 7 | 0 | 30 | 4 | 66 | 66 | 43 | 48% | 498 | 14s | $0.74 |
| Gemini 3.8 Flash (high) | 11 | 7 | 5 | 6 | 0 | 29 | 0 | 71 | 1 | 30 | 93% | 16,220 | 142s | $6.17 |
| Gemini 3.8 Flash (medium) | 9 | 6 | 5 | 7 | 0 | 27 | 1 | 72 | 5 | 29 | 92% | 7,624 | 68s | $2.95 |
| GPT-6.1 Sol (xhigh) | 11 | 6 | 5 | 4 | 0 | 26 | 4 | 70 | 0 | 26 | 48% | 1,220 | 54s | $1.47 |
| GPT-6.1 Sol (high) | 10 | 6 | 5 | 2 | 0 | 23 | 2 | 75 | 0 | 24 | 47% | 515 | 29s | $0.77 |
| GPT-6 Astra (xhigh) | 9 | 6 | 5 | 2 | 0 | 22 | 2 | 76 | 0 | 23 | 44% | 805 | 42s | $5.28 |
| GPT-6 Astra (high) | 9 | 4 | 4 | 4 | 0 | 21 | 6 | 73 | 0 | 21 | 46% | 338 | 23s | $2.94 |
| Claude Sonnet 5.5 (xhigh) | 9 | 5 | 4 | 2 | 0 | 20 | 4 | 76 | 68 | 30 | 29% | 1,017 | 11s | $1.29 |
| GPT-6.1 Sol (low) | 8 | 6 | 4 | 2 | 0 | 20 | 2 | 78 | 1 | 20 | 47% | 192 | 17s | $0.44 |
| GPT-6 Astra (medium) | 8 | 5 | 3 | 1 | 0 | 17 | 2 | 81 | 0 | 17 | 43% | 196 | 16s | $2.23 |
| Grok 4.7 (high) | 6 | 4 | 5 | 2 | 0 | 17 | 2 | 81 | 4 | 17 | 57% | 17,095 | 356s | $10.72 |
| GPT-6.1 Sol (medium) | 6 | 5 | 4 | 1 | 0 | 16 | 3 | 81 | 1 | 16 | 45% | 282 | 18s | $0.53 |
| GPT-6 Astra (low) | 7 | 3 | 4 | 2 | 0 | 16 | 2 | 82 | 0 | 16 | 43% | 173 | 17s | $2.12 |
| Claude Sonnet 5.5 (high) | 7 | 4 | 3 | 1 | 0 | 15 | 4 | 81 | 67 | 23 | 34% | 725 | 9s | $1.00 |
| Grok 4.7 (medium) | 6 | 2 | 3 | 4 | 0 | 15 | 2 | 83 | 0 | 15 | 56% | 11,163 | 226s | $7.16 |
| Gemini 3.8 Flash (low) | 8 | 2 | 2 | 3 | 0 | 15 | 1 | 84 | 11 | 16 | 87% | 1,118 | 20s | $0.51 |
| Grok 4.7 (xhigh) | 4 | 2 | 5 | 2 | 0 | 13 | 1 | 86 | 3 | 13 | 57% | 21,535 | 418s | $13.39 |
| Claude Sonnet 5.5 (low) | 3 | 4 | 3 | 1 | 0 | 11 | 4 | 85 | 65 | 22 | 47% | 331 | 6s | $0.61 |
| Claude Sonnet 5.5 (medium) | 3 | 3 | 2 | 2 | 0 | 10 | 6 | 84 | 62 | 15 | 36% | 455 | 7s | $0.73 |
| Grok 4.7 (low) | 3 | 3 | 3 | 1 | 0 | 10 | 3 | 87 | 1 | 11 | 56% | 3,225 | 79s | $2.40 |
| Claude Haiku 5.5 (medium) | 3 | 6 | 0 | 0 | 0 | 9 | 2 | 89 | 56 | 13 | 52% | 892 | 7s | $0.06 |
| GPT-6 Luna (xhigh) | 3 | 4 | 2 | 0 | 0 | 9 | 1 | 90 | 4 | 9 | 50% | 1,458 | 25s | $0.09 |
| Claude Haiku 5.5 (low) | 4 | 3 | 0 | 0 | 0 | 7 | 2 | 91 | 55 | 12 | 49% | 738 | 7s | $0.05 |
| Claude Haiku 5.5 (high) | 3 | 3 | 0 | 1 | 0 | 7 | 2 | 91 | 55 | 15 | 53% | 1,316 | 9s | $0.08 |
| Claude Haiku 5.5 (xhigh) | 3 | 3 | 1 | 0 | 0 | 7 | 1 | 92 | 59 | 16 | 53% | 3,020 | 17s | $0.16 |
| GPT-6 Luna (high) | 1 | 5 | 1 | 0 | 0 | 7 | 1 | 92 | 2 | 7 | 46% | 818 | 16s | $0.05 |
| GPT-6 Luna (low) | 0 | 3 | 0 | 0 | 0 | 3 | 3 | 94 | 3 | 3 | 40% | 25 | 8s | $0.01 |
| GPT-6 Luna (medium) | 0 | 2 | 0 | 0 | 0 | 2 | 1 | 97 | 1 | 2 | 39% | 29 | 5s | $0.01 |
Hedged: answers that offered more than one candidate. Listed: answers where the right identification appeared anywhere, even as a second guess. Conf.: average confidence the model stated. Tokens: output tokens per answer, thinking included. Cost: the whole run of 100 clips at API list prices. No model refused a clip.
- Every model ran through its maker's own agent CLI on a subscription, at each reasoning effort from low to xhigh, told to answer straight from the image with no tools. Antigravity and Cursor have no way to attach an image, so those models opened the one image file themselves; none made any other tool call.
- Grading is strict. Naming the right kind of sound is not enough: "a person saying hello" is wrong for any other word or sentence. A near miss is a closely related sound, a neighbouring instrument family, or a word one sound away. Words and sentences are scored by rule; the other tiers were read and scored by Claude Opus 5.5, which is also on the board.
- An effort level is not the same amount of thinking everywhere: the table's token column shows how much each model wrote and thought per answer. No model was run at max effort.
- Clips come from ESC-50 (K. J. Piczak, CC BY-NC), NSynth (Google Magenta, CC BY 4.0), VocalSound (Gong, Yu and Glass, CC BY-SA 4.0), Speech Commands (P. Warden, CC BY 4.0) and LibriSpeech (Panayotov et al., CC BY 4.0). Run on 13 October 2026.